



Spark SQL
Apache Spark's module for querying structured data using SQL or DataFrame API, integrated with Spark programs and supporting multiple data sources.
Score
30
User Rating
3.0
Free/Trial Support
Not Supported
Starting Price
--
Last Updated
Aug 04, 2026
Overview
What is Spark SQL?
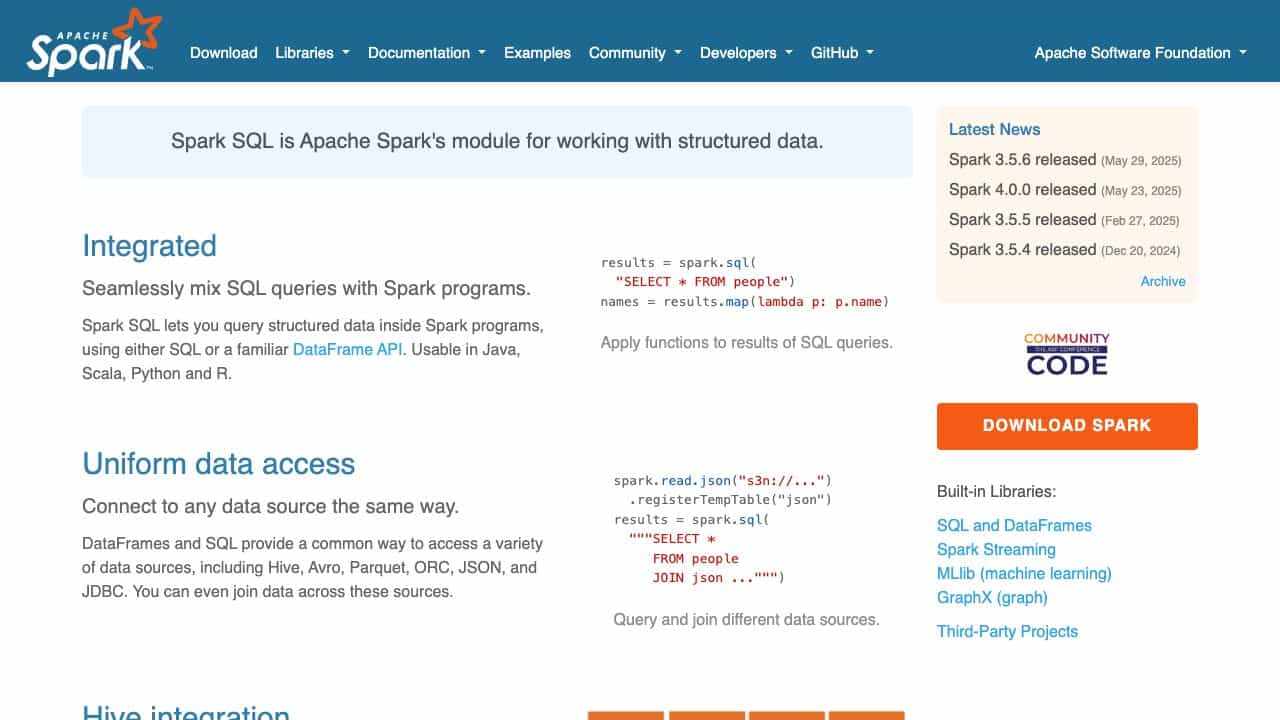
Spark SQL is a module of Apache Spark designed for processing structured data. It allows users to run SQL queries seamlessly within Spark applications, using either SQL syntax or a DataFrame API. It supports integration with various data sources like Hive, JSON, Parquet, and JDBC/ODBC, and includes performance features such as cost-based optimization and columnar storage.
What is Spark SQL used for?
Top Features
- Integrated SQL queries with Spark programs
- Uniform data access across multiple sources
- Hive integration for existing warehouses
- JDBC/ODBC connectivity for BI tools
- Performance optimization with cost-based optimizer and columnar storage
How to use Spark SQL?
Download Apache Spark, which includes Spark SQL. Use the Spark SQL or DataFrame guide to learn the API. Write queries in SQL or use the DataFrame API in Java, Scala, Python, or R to access and join data from multiple sources like Hive, JSON, or JDBC.
Alternative Tools
No alternative tools found
Pros & Cons
Pros
- Seamless integration with Spark
- Supports multiple programming languages
- High scalability and fault tolerance
- Free and open-source under Apache License
Cons
- Requires learning Spark ecosystem
- May have a steep learning curve for beginners
Use Cases
- Big data analytics and querying
- Data integration from diverse sources
- Business intelligence reporting
- Machine learning data preprocessing
User Reviews
3.0
out of 5
3.0
No reviews yet
Be the first to review this tool!