



CMU Q/A Dataset
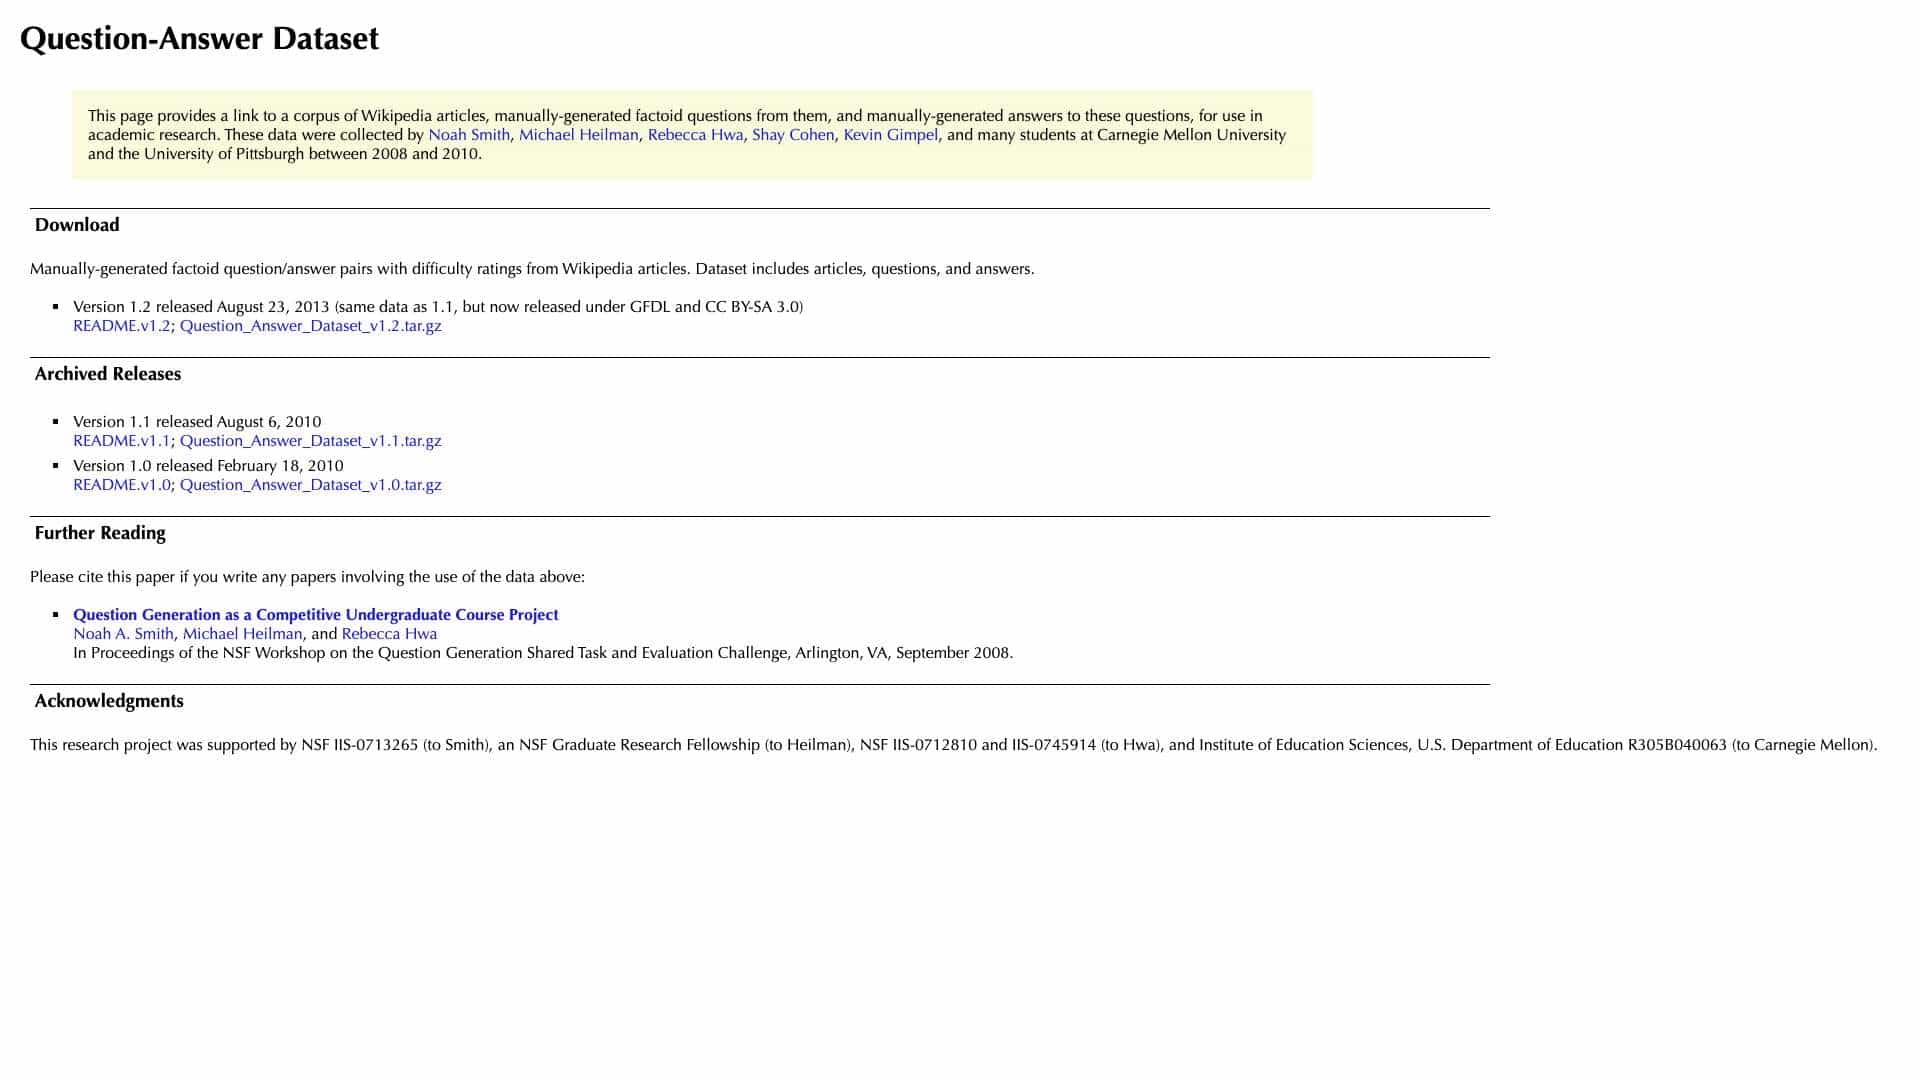
A dataset of Wikipedia articles with manually-generated factoid questions and answers for academic research, collected between 2008-2010.
Score
30
User Rating
3.0
Free/Trial Support
Supported
Starting Price
--
Last Updated
Apr 23, 2026
Overview
What is CMU Q/A Dataset?
This is a corpus of Wikipedia articles paired with manually-created factoid questions and answers, designed for use in academic research on question generation and answering. It includes difficulty ratings and multiple versions released under open licenses.
What is CMU Q/A Dataset used for?
Top Features
- Wikipedia articles
- Manually-generated questions
- Manually-generated answers
- Difficulty ratings
- Multiple versions available
- Open licenses (GFDL, CC BY-SA)
How to use CMU Q/A Dataset?
Download the dataset files (e.g., tar.gz archives) from the provided links, extract them, and use the articles, questions, and answers for research projects, such as training or evaluating natural language processing models.
Alternative Tools
No alternative tools found
Pros & Cons
Pros
- High-quality manual annotations
- Useful for NLP research
- Free to download and use
- Includes academic citations
Cons
- Data from 2008-2010 may be outdated
- Limited to factoid questions
- No active updates or support
Use Cases
- Academic research on question answering
- Training machine learning models
- Educational projects in NLP courses
CMU Q/A Dataset Pricing
Free Plan
No detailed pricing information available
User Reviews
3.0
out of 5
3.0
No reviews yet
Be the first to review this tool!