



ApacheTajo
Apache Tajo is a distributed big data warehouse system on Hadoop for low-latency SQL queries, ETL, and scalable data processing.
Score
30
User Rating
3.0
Free/Trial Support
Not Supported
Starting Price
--
Last Updated
Aug 04, 2026
Overview
What is ApacheTajo?
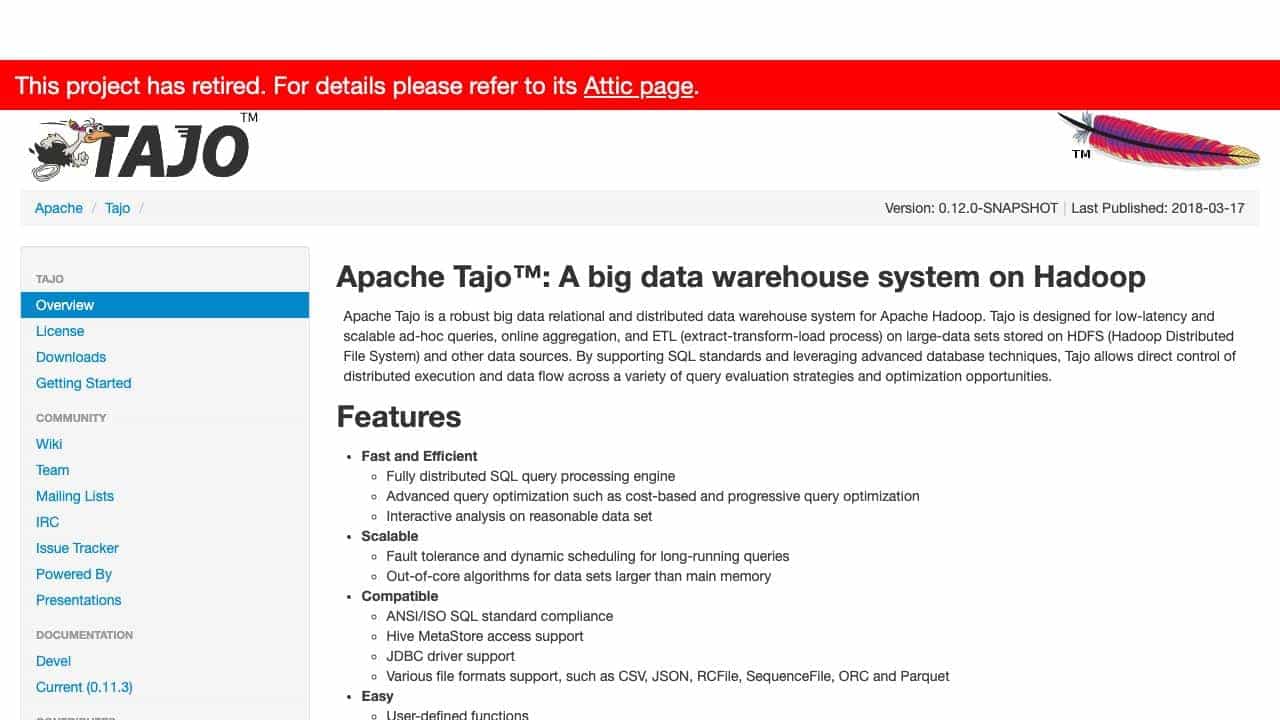
Apache Tajo is a robust big data relational and distributed data warehouse system designed for Apache Hadoop. It supports SQL standards, enables low-latency ad-hoc queries, online aggregation, and ETL on large datasets stored on HDFS and other sources, with advanced query optimization and fault tolerance.
What is ApacheTajo used for?
Top Features
- Distributed SQL query processing
- Advanced query optimization
- Fault tolerance and dynamic scheduling
- ANSI/ISO SQL compliance
- Support for various file formats
- User-defined functions
- Interactive shell
- JDBC driver support
How to use ApacheTajo?
Deploy Tajo on Hadoop clusters, use SQL for querying data, leverage JDBC for connectivity, and utilize its interactive shell and APIs for data processing and analysis on big data sets.
Alternative Tools
No alternative tools found
Pros & Cons
Pros
- Scalable for big data
- Low-latency queries
- Open-source and free
- Compatible with Hadoop ecosystem
- Supports multiple data sources
Cons
- Retired project (no active development)
- Requires Hadoop infrastructure
- Steep learning curve for beginners
Use Cases
- Big data analytics and reporting
- ETL processes on Hadoop
- Interactive data exploration
- Data warehousing for enterprises
User Reviews
3.0
out of 5
3.0
No reviews yet
Be the first to review this tool!